

Machine Learning Fundamentals Course Roadmap for Beginners
Master the essentials of AI with this machine learning fundamentals course roadmap for beginners, designed to take you from novice to coding.
 Nitesh Roy
6 min read
Key takeaways
- Start with basic linear algebra and statistics before advanced algorithms.
- Master Python and core libraries like NumPy and Pandas early.
- Build hands-on projects and publish them on GitHub for practice.
- Differentiate clearly between supervised and unsupervised learning techniques.
On this page
Starting out with a machine learning fundamentals course roadmap for beginners can feel overwhelming when every tutorial demands a master’s degree in math. This guide cuts through the noise to give you a clear, step-by-step path to building predictive models from scratch. Whether you want to transition into tech or simply understand how modern software makes decisions, mastering the core concepts requires a structured approach.
Why start with the basics of machine learning?
Understanding the shift from traditional programming to data-driven algorithms
Traditional software engineering relies on strict rules written by humans. You give a program inputs and instructions, and it spits out an output. Machine learning flips this model entirely by feeding computers data and expected answers so the system can write its own rules. This paradigm shift means you are no longer coding every single logical branch. Instead, you are designing architectures that learn patterns on their own.
Identifying real-world applications of predictive models in daily software
You interact with machine learning models every single day without realizing it. Recommendation engines on streaming services, spam filters in your inbox, and predictive text on your phone all rely on these algorithms. Recognizing how these systems operate behind the scenes helps demystify the technology. Once you see the underlying patterns in everyday apps, abstract algorithms become much easier to visualize and build.
Setting realistic expectations for time investment and math requirements
Many beginners stall out because they think they need to memorize every statistical theorem before writing a line of code. In reality, you can build working models with a foundational grasp of algebra and calculus. Expect to spend several months building consistency rather than chasing overnight mastery. Balancing hands-on coding with conceptual study prevents burnout and keeps your momentum high.
What essential math and statistics do you actually need?
Focusing on linear algebra essentials like vectors and matrix multiplication
Data in machine learning is rarely just a single number; it lives inside massive grids called matrices and vectors. Linear algebra gives you the tools to transform, manipulate, and compute these multidimensional datasets efficiently. You do not need to prove complex theorems from scratch, but you do need to understand how matrix multiplication drives neural network operations.
Grasping basic probability distributions and descriptive statistics
Uncertainty is a core part of working with data. Descriptive statistics help you summarize large datasets using mean, median, variance, and standard deviation. Probability distributions allow you to model how likely certain events are to happen, which is critical when your algorithms make predictions under uncertainty.
Learning calculus fundamentals for optimization and gradient descent
How does a model actually improve over time? Calculus provides the answer through derivatives and partial derivatives. Optimization algorithms use these mathematical concepts to calculate error rates and nudge the model parameters in the right direction. Gradient descent relies entirely on these principles to find the lowest point on a loss curve.
Which programming language should you learn first?
Evaluating Python as the undisputed industry standard for AI and data science
Python has won the artificial intelligence race by a landslide due to its readable syntax and massive community support. Its clean structure looks almost like plain English, making it friendly for absolute beginners. Because almost every major machine learning framework is built for Python, it is the most practical choice for your starting language.
Mastering core syntax, data structures, and object-oriented programming
Before jumping into complex algorithms, spend time getting comfortable with basic programming concepts. Learn how to write loops, handle conditionals, and manage data structures like lists, dictionaries, and sets. Understanding object-oriented programming will also help you navigate existing codebases and build your own reusable modules.
Exploring essential libraries like NumPy, Pandas, and Matplotlib
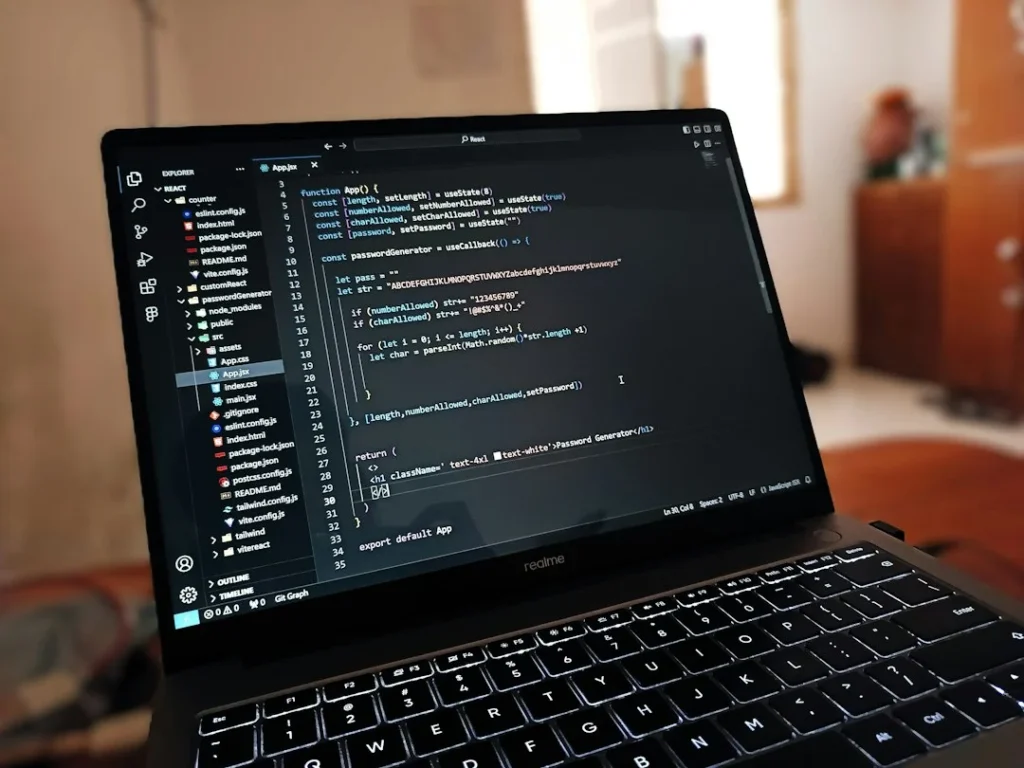
Writing machine learning models from scratch in pure Python is painfully slow. Libraries like NumPy give you lightning-fast array operations, while Pandas makes cleaning and manipulating tabular data effortless. Matplotlib and Seaborn round out your toolkit by allowing you to visualize trends, correlations, and model performance visually.
How do you master core machine learning algorithms?
Differentiating between supervised and unsupervised learning techniques
Supervised learning involves training a model on labeled data, meaning the correct answers are provided during the learning phase. Classification and regression fall neatly into this category. Unsupervised learning, on the other hand, deals with unlabeled data where the algorithm must find hidden structures or groupings on its own, such as customer segmentation.
Implementing linear regression and logistic regression from scratch
Linear regression is your gateway model for predicting continuous numeric values, like house prices. Logistic regression adapts this concept for classification tasks, such as predicting whether an email is spam or not spam. Implementing these simple models without heavy libraries first gives you deep intuition into how parameters adjust during training.
Understanding decision trees, random forests, and k-nearest neighbors
Decision trees split data based on feature conditions, mimicking human-like flowchart decisions. Random forests combine hundreds of these trees together to improve accuracy and prevent overfitting. Meanwhile, k-nearest neighbors classifies new data points based on how close they are to known points in a feature space.
How to build a portfolio with hands-on projects
Selecting beginner-friendly datasets from public repositories like Kaggle
Theory alone will not land you projects or jobs; building things will. Public repositories host thousands of clean, well-documented datasets ranging from titanic survival rates to housing markets. Pick datasets that match your personal interests to keep the learning process engaging.
Cleaning, preprocessing, and exploratory data analysis best practices
Raw data is almost always messy, containing missing values, typos, and outliers. Spending time on exploratory data analysis lets you uncover hidden biases and trends before touching any modeling code. Learning how to handle missing data and scale features properly separates working models from broken ones.
Documenting your code and publishing your final projects on GitHub
A folder of messy scripts on your desktop helps nobody. Writing clear README files, commenting your code, and publishing your work on GitHub demonstrates your technical communication skills. If you want structured feedback on your practical projects, exploring foundation internship programs can help bridge the gap between solo learning and collaborative engineering.
Step-by-Step Implementation
- Install Python and Jupyter Notebook: Set up your local development environment using Anaconda or standard pip to run interactive code cells.
- Learn basic NumPy and Pandas: Practice loading small CSV files, filtering rows, and performing vector operations in your terminal or notebook.
- Plot your first dataset: Use Matplotlib or Seaborn to create scatter plots and histograms that reveal relationships between different data columns.
- Build a linear regression model: Use Scikit-Learn to train a simple predictive model on a housing or sales dataset and evaluate its error rate.
- Publish your first repository: Clean up your code comments, write a short project description, and push your Jupyter notebook to a public GitHub profile.
Frequently asked questions
Do I need a strong math background to start learning machine learning?
No, you do not need an advanced math degree to get started. High school algebra and basic statistics are enough to understand foundational algorithms. You can learn the heavier mathematical concepts gradually as you encounter them in your coding projects.
How long does it take to learn machine learning fundamentals?
Most beginners need about three to six months of consistent daily practice to grasp the core fundamentals. The exact timeline depends on your prior coding experience and how much time you dedicate each week to hands-on projects.
Can I learn machine learning without knowing Python?
While other languages like R or Julia are used in specific data niches, Python remains the absolute industry standard. Choosing Python gives you access to the largest collection of tutorials, libraries, and community support available.
What is the difference between artificial intelligence and machine learning?
Artificial intelligence is a broad umbrella term for any computer system that mimics human intelligence. Machine learning is a specific subset of AI focused on algorithms that learn patterns from data rather than relying on hardcoded rules.
Next Steps
- Download Python and set up your beginner development workspace today.
- Pick one introductory dataset on Kaggle and explore its columns.
- Commit to writing code for at least thirty minutes every single day.
Photo by litoon dev on Unsplash · Photo by Naman Rai on Unsplash
 Skills & Courses
 Skills & Courses
 Skills & Courses
