

Python and Machine Learning Interview Questions for Beginners
Master essential Python and machine learning interview questions for beginners to land your first data role with confidence and practical prep.
 Nitesh Roy
9 min read
Key takeaways
- Master mutable and immutable data types in Python before your interview.
- Explain supervised and unsupervised learning concepts in plain English.
- Handle missing values and feature scaling correctly using Pandas and Scikit-learn.
- Communicate your thought process clearly during live coding challenges.
- Build end-to-end predictive models with real-world datasets for your portfolio.
On this page
Quick Summary
- Prepare for your first data science job by practicing fundamental Python and Machine Learning Interview Questions for Beginners.
- Learn how to explain core Python data structures, list comprehensions, and basic machine learning algorithms with confidence.
- Master essential data preprocessing techniques using popular libraries like Pandas and Scikit-learn.
- Discover how to structure your GitHub portfolio and communicate your thought process during live coding tests.
Walking into your first data science interview can feel pretty overwhelming, especially when you are trying to remember every single algorithm and syntax rule. Practicing Python and Machine Learning Interview Questions for Beginners gives you the structure you need to walk into that room calm and prepared. Let’s break down the exact concepts, coding questions, and portfolio strategies you need to know to land your first role.
What core Python concepts do interviewers test first?
Understanding mutable versus immutable data types in Python
Interviewers love asking about mutability because it exposes whether you truly understand how Python stores objects in memory. Mutable objects like lists, dictionaries, and sets can be changed after they are created without altering their memory address. Immutable objects like strings, tuples, and integers cannot be changed, meaning any modification creates a brand new object in memory.
When you pass a list into a function, any changes you make inside that function affect the original list outside of it. Passing a tuple or integer, however, keeps the original data safe because Python treats it as a read-only value. Getting this concept right early in the interview shows you understand how to avoid sneaky bugs in your data pipelines.
Writing clean list comprehensions and lambda functions efficiently
Writing clean code is just as important as writing working code during a python programming interview for freshers. List comprehensions offer a readable, compact way to create new lists based on existing iterables. Instead of writing a bulky four-line for-loop with an append method, you can usually write the exact same logic in a single expressive line.
Lambda functions are small anonymous functions defined with the lambda keyword, usually used for short, throwaway operations. They pair up beautifully with built-in functions like filter, map, and sorting keys in Pandas DataFrames. Keeping your anonymous functions short and readable ensures your teammates can maintain your code without scratching their heads.
How do you explain fundamental machine learning algorithms?
Differentiating between supervised and unsupervised learning clearly
When interviewers ask about basic ml algorithms questions, they want to hear clear, jargon-free explanations. Supervised learning involves training a model on labeled data, meaning every input comes with a known correct output. Think of it like teaching a child to recognize cats by showing them photos explicitly labeled as cats.
Unsupervised learning deals with unlabeled data where the algorithm tries to find hidden patterns or natural groupings on its own. Clustering algorithms like K-Means are classic examples of unsupervised learning because they group similar data points without human intervention. Knowing when to use each paradigm is a fundamental skill for any entry-level data practitioner.
Explaining linear regression and logistic regression in simple terms
Linear regression is your go-to tool for predicting continuous numerical values, like housing prices or daily temperatures. It works by fitting a straight line through your data points that minimizes the overall distance between the actual values and the predicted line. It is simple, interpretable, and serves as the baseline for many complex statistical models.
Logistic regression sounds similar, but it solves classification problems instead of predicting numbers. It calculates the probability that a given input belongs to a specific category, usually outputting a value between zero and one. You use it when you want a yes-or-no answer, such as predicting whether an email is spam or not.
What are the essential data preprocessing steps in Python?
Handling missing values using Pandas and Scikit-learn
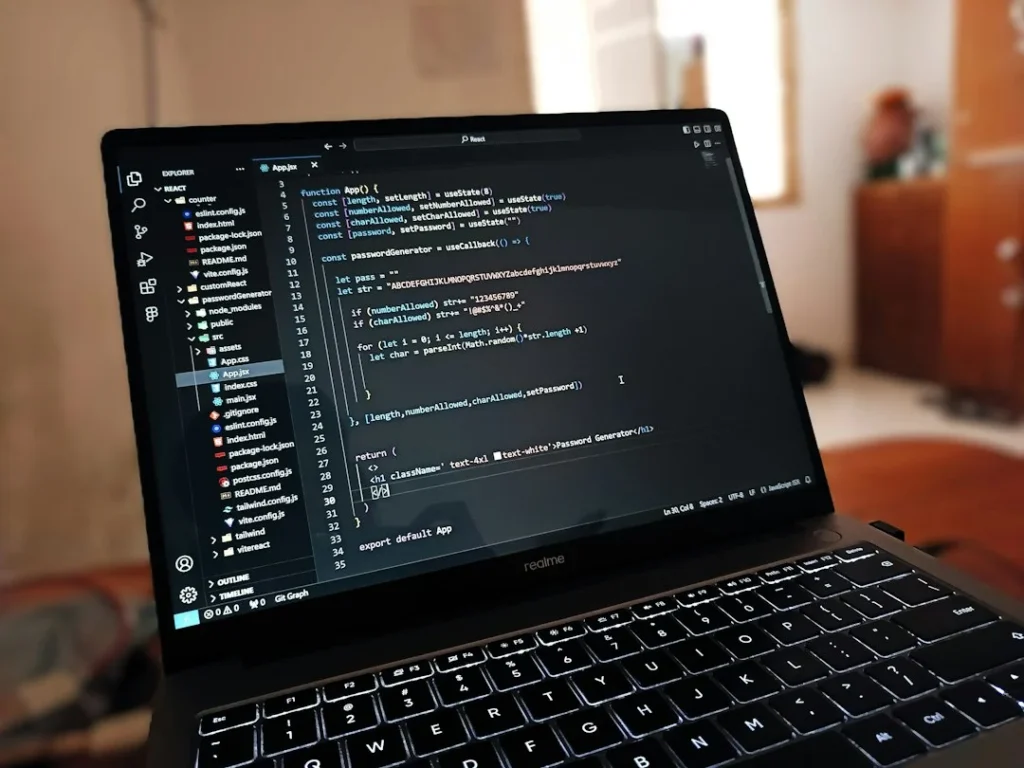
Real-world data is messy, incomplete, and rarely ready to feed straight into an algorithm. During your data science coding interview prep, you will need to demonstrate how you find and fix missing values using Pandas methods like isnull().sum() and dropna() or fillna(). Leaving missing data unhandled will cause most machine learning libraries to throw errors immediately.
For more advanced workflows, Scikit-learn provides the SimpleImputer class to fill missing numerical entries with the mean, median, or most frequent value. Choosing how to handle missing data depends heavily on your dataset size and the context of the problem you are solving. Always justify your choice to the interviewer so they know you are thinking critically.
Feature scaling techniques like standardization and normalization
Many machine learning algorithms perform poorly when your input features have wildly different scales and units. For instance, an income feature ranging in the hundreds of thousands will completely overpower an age feature ranging from zero to one hundred. Standardization shifts your data to have a mean of zero and a standard deviation of one using Scikit-learn’s StandardScaler.
Normalization, on the other hand, rescales all your feature values to fit neatly into a fixed range between zero and one. Distance-based algorithms like K-Nearest Neighbors and gradient descent models rely heavily on proper scaling to converge efficiently. Applying these transformations prevents larger numerical values from biasing your model during training.
How should you approach live coding challenges?
Communicating your thought process clearly while writing code
Interviewers care much more about how you think than whether you memorize syntax word-for-word. When you get a live coding prompt, resist the urge to start typing in absolute silence. Talk through your assumptions, repeat the problem back in your own words, and explain why you are choosing a specific data structure.
If you hit a roadblock, take a deep breath and vocalize where you think the bug might live. Collaborative problem-solving lets the interviewer guide you with gentle hints rather than watching you stare blankly at a screen. Clear communication turns a stressful technical test into a natural engineering conversation.
Writing modular functions with proper error handling and edge cases
Writing spaghetti code inside a single giant block is a quick way to lose points during a live technical assessment. Break your solution down into small, single-purpose functions with descriptive names and clear docstrings. This modular approach makes your code much easier to debug and test piece by piece.
Always check for edge cases before finishing your solution, such as empty lists, negative numbers, or unexpected data types. Adding basic input validation or try-except blocks shows that you write robust code built for real production environments. Employers love candidates who think defensively about what could go wrong.
What portfolio projects make a beginner stand out?
Building end-to-end predictive models with real-world datasets
Building a predictive model from scratch proves you can take a project from raw data to a working prototype. Pick a dataset that genuinely interests you, whether it is sports statistics, customer churn data, or public health metrics. Clean the data, engineer new features, train multiple models, and evaluate them using appropriate metrics.
An end-to-end project demonstrates that you understand the entire machine learning lifecycle, not just isolated textbook theories. When you participate in structured programs like our Foundation Internship Programs, you gain hands-on experience building these exact types of production-ready applications. Being able to talk through the challenges you faced during development makes for an incredible interview talking point.
Structuring GitHub repositories with clean README documentation
Your GitHub profile is often the very first resume an engineering manager looks at. A messy repository with unorganized scripts and zero documentation tells recruiters you do not care about code hygiene. Make sure every project includes a professional README explaining the problem statement, installation steps, and model performance results.
Organize your repository with clear folder structures, keeping raw data, notebooks, and source scripts neatly separated. Clean documentation shows professionalism and allows anyone to clone your project and run it without confusion. If you want to explore more career resources, visit the VELYON Insights – Blog & Knowledge Hub for additional tips on breaking into tech.
Step-by-Step Implementation
- Do this: Set up a dedicated virtual environment using venv or Conda to keep your project dependencies clean and isolated. This prevents package version conflicts when sharing your code or deploying models.
- Do this: Load your dataset into a Pandas DataFrame and run basic inspection commands like info() and describe() to check data types and summary statistics. This helps you catch anomalies early.
- Do this: Clean your data by identifying missing values, dropping duplicate rows, and converting categorical text columns into numerical formats using one-hot encoding. Clean inputs lead to stable model training.
- Do this: Split your dataset into training and testing sets using Scikit-learn’s train_test_split function to prevent data leakage and evaluate real-world performance accurately.
- Do this: Train a simple baseline model, such as Logistic Regression or Decision Trees, and evaluate it using precision, recall, or mean squared error metrics. Establishing a baseline gives you something to beat with more complex models.
- Do this: Write clean, reusable Python functions with proper docstrings and exception handling for any custom data transformation steps you perform. Modular code is easier to maintain and test.
- Do this: Document your entire workflow inside a well-structured Jupyter Notebook or Python script with clear Markdown headings explaining your decisions. Good documentation showcases your analytical thinking.
- Do this: Push your finished project to a public GitHub repository accompanied by a detailed README file explaining how to install and run your code. This creates a shareable asset for your professional portfolio.
Frequently asked questions
What programming language is best for machine learning interviews?
Python is the undisputed industry standard for entry-level machine learning interviews due to its readability and massive ecosystem of data science libraries like Pandas, NumPy, and Scikit-learn.
Do I need a computer science degree to pass machine learning interviews?
No, many successful data scientists come from diverse backgrounds such as mathematics, physics, economics, or self-taught software engineering, provided they can demonstrate solid coding and problem-solving skills.
How should I prepare for live coding interviews if I get nervous?
Practice mock interviews with peers, talk through your code out loud while studying, and focus on explaining your logic step by step rather than rushing to write perfect syntax.
What machine learning projects are best for an entry-level resume?
Projects that solve real-world problems using messy public datasets stand out far more than generic Titanic or Iris flower classification tutorials found in every online course.
Next Steps
Now that you know what interviewers look for, pick one beginner dataset today and build a complete predictive model from scratch. Document your code on GitHub, review your Python fundamentals, and keep practicing your technical explanations.
Photo by Stephen Harlan on Unsplash · Photo by Naman Rai on Unsplash
Build your career with VELYON
Related reading
 Interview PrepScenario-Based SEO Interview Questions to Ace Your Next Job8 min read · November 12, 2026
 Interview PrepHow to Answer Practical Experience Questions as a Fresher8 min read · November 10, 2026
 Interview PrepHow to Explain Portfolio Projects Confidently in Interviews9 min read · November 8, 2026
